Quick animation intro
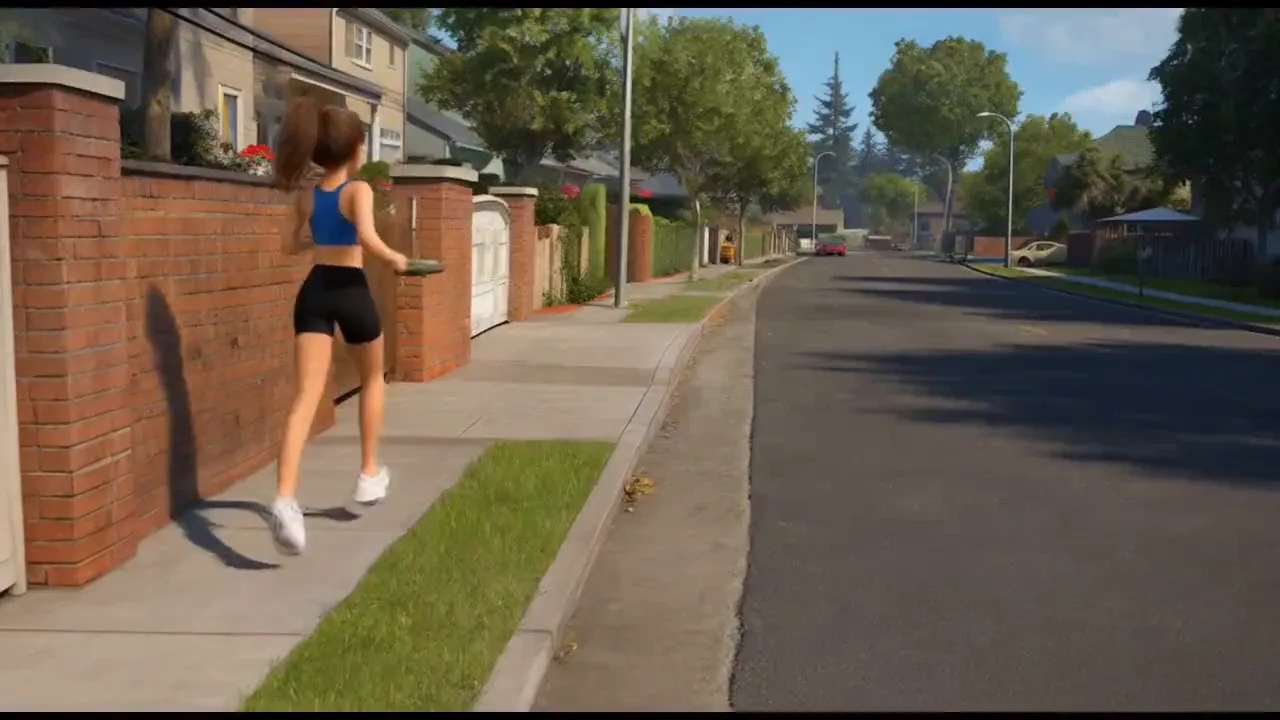
Hey hey, just something I made with Maestro, not finished, this is just the opening, but I'm pretty happy with the results, thought I'd share it with the community :)
Hey hey, just something I made with Maestro, not finished, this is just the opening, but I'm pretty happy with the results, thought I'd share it with the community :)
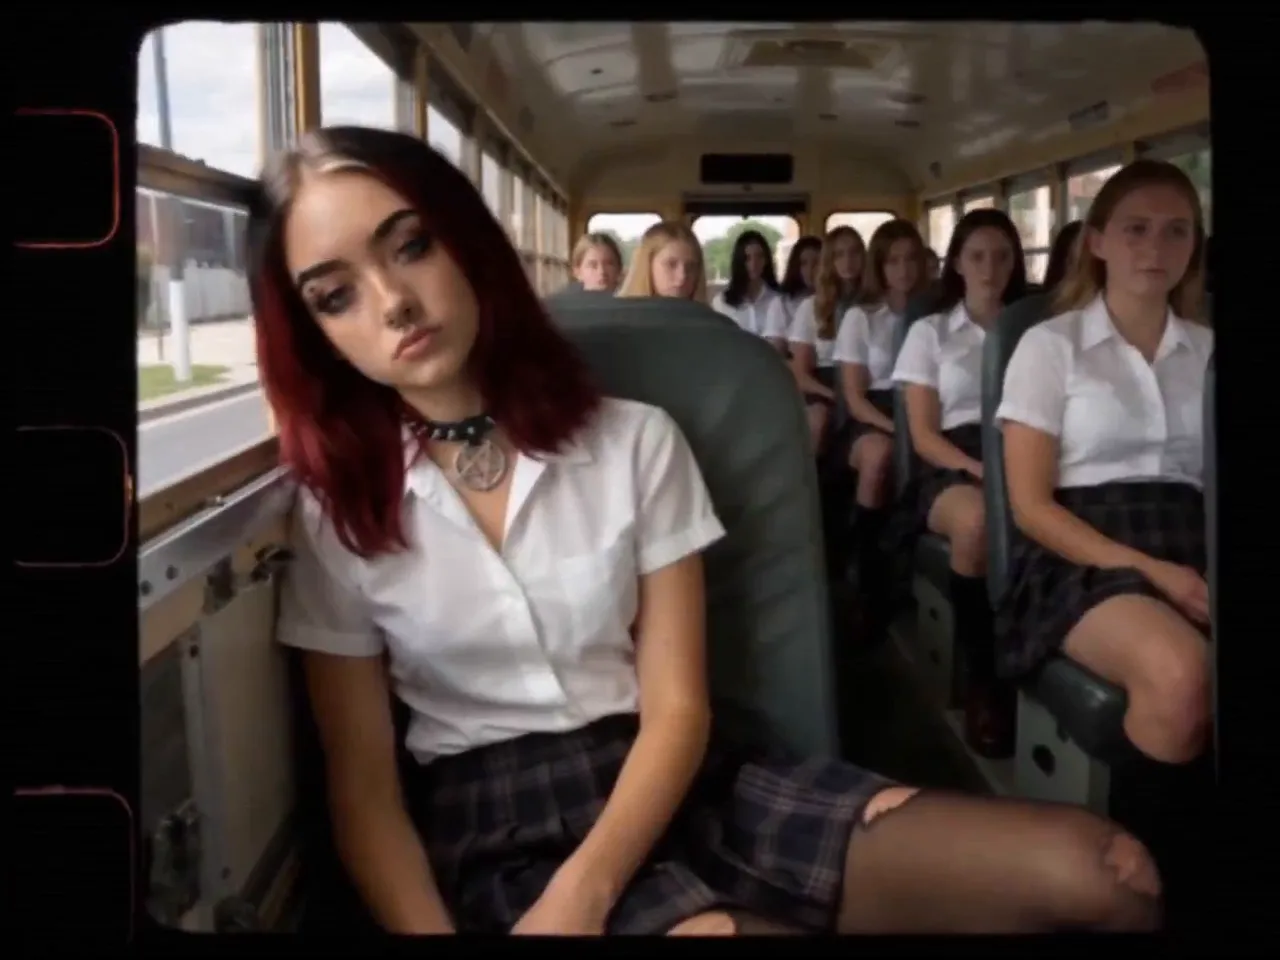
Hey hey :) Been working on a new music video, learned a bit since the last one, haven't quite finished this one yet, but pretty happy with how it's turning out so far, this was pretty heavily compressed to fit into the post so the CRT scanlines and whatnot aren't really visible here, though I may actually end up posting this to YT when I finish
So, I've been doing a little poking around myself, as having 32gb vram means I could run the LLM on the CUDA option, if it were set up properly, so --- "Change (CUDA\d+) to ((?:CUDA|ROCm)\d+) in llama_linux_runtime.py and bundle the Lemonade SDK ROCm llama-server binary" - dunno if that's helpful at all, but it has worked for me at least, running a 27b LLM on CPU was taking.... around 2-3 hours to do a big prompt, after changing these settings, same prompt, about 5 minutes, possible you may want to add that yourself at some point, or something along the same lines for running the LLM on GPU, s
What happened? whatever blizaine added with the Yue2 update, loks like he added new H3 checkpoints, and the wgp.py code is bringing up errors related to tagging of architecture Steps to reproduce update Maestro AMD, start. Your system (OS / GPU / RAM / VRAM / etc.) Ubuntu / Radeon AI Pro 9700 / 32gb vram / 64gb ram / Ryzen 9 5900x Logs / full error output Paste the full log output here ████ ██ Starting Shell 678f1554-39d4-418e-81bf-62cd15e8f41c <<PINOKIO_SHELL>>eval "$(conda shell.bash hook)" ; conda deactivate ; conda deactivate ; conda deactivate ; conda activate base ; source /home/mj84/pin