Radar
New projects people are discovering or following across Pinokio.
Discovered9d ago
hypitClone any viral video with AI agents. Not just a script, the whole workflow: swap the face, the words, the B-roll, ship 100 variants in one command, and get your 100M views.
Followed9d ago
AudioSepSeparate Anything You Describe (https://huggingface.co/spaces/Audio-AGI/AudioSep)
Followed9d ago
Z-Image-Turbo-LowVram-Edition⚡️ Efficient 6B parameter image generation model with sub-second inference. Generate high-quality, photorealistic images with only 8 inference steps. Features bilingual text rendering (Chinese & English) and Single-Stream Diffusion Transformer architecture.Minimum 4GB graphics memory is supported.
Followed9d ago
Iris-3BPixel-space text-to-image generation (no VAE), monocular depth estimation and 4x image restoration/upscaling with Iris-3B by Speridlabs
Discovered9d ago
OpenSuno-YuE2OpenSuno-YuE2: local music generation studio for the YuE2 model on Apple Silicon and Windows/NVIDIA, with automatic model downloads.
Followed9d ago
Bounty HunterPut the model you already run to work. It reads a public support board, writes an answer, and earns USDC when a human approves it. Starts in a dry run, so looking costs nothing.
Followed9d ago
DiaDia is a 1.6B parameter text to speech model created by Nari Labs. Dia directly generates highly realistic dialogue from a transcript. You can condition the output on audio, enabling emotion and tone control. The model can also produce nonverbal communications like laughter, coughing, clearing throat, etc. https://github.com/nari-labs/dia
Followed9d ago
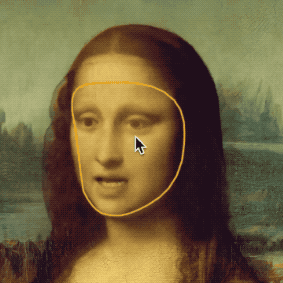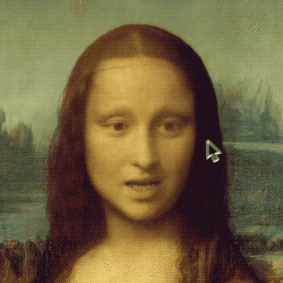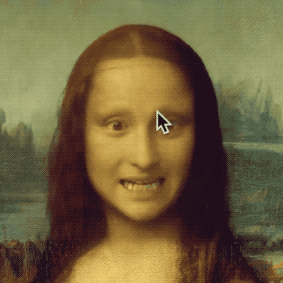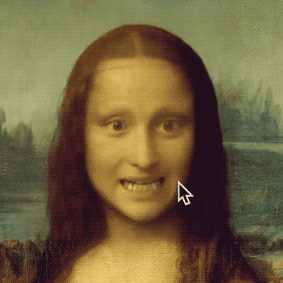
facepoke[NVIDIA Only] Select a portrait, click to move the head around https://github.com/jbilcke-hf/FacePoke
Discovered9d ago
claude-youtubeClaude Code skill for YouTube creators — channel audits, video SEO, retention scripts, thumbnails, content strategy, Shorts optimization, analytics, monetization, and more.
Followed9d ago
InstantMeshInstantMesh: Efficient 3D Mesh Generation from a Single Image with Sparse-view Large Reconstruction Models
Followed9d ago
DocToSpeechFully offline document-to-speech converter supporting 9 TTS models across 5 engine groups: Coqui (XTTS v2, Bark, VITS, YourTTS), StyleTTS 2, Resemble Chatterbox, Tortoise TTS, Sesame CSM-1B, and OpenVoice V2. Converts EPUB, PDF, DOCX, HTML, and TXT files to audio with voice cloning support. No API keys or cloud services required.
Discovered9d ago
azeroth-survivors-reA survivors roguelite running on a from-scratch World of Warcraft 1.12.1 client engine (Rust + Bevy).
Followed9d ago
F5-TTSOfficial code for "F5-TTS: A Fairytaler that Fakes Fluent and Faithful Speech with Flow Matching"
Discovered9d ago
DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF · Hugging FaceWe’re on a journey to advance and democratize artificial intelligence through open source and open science.