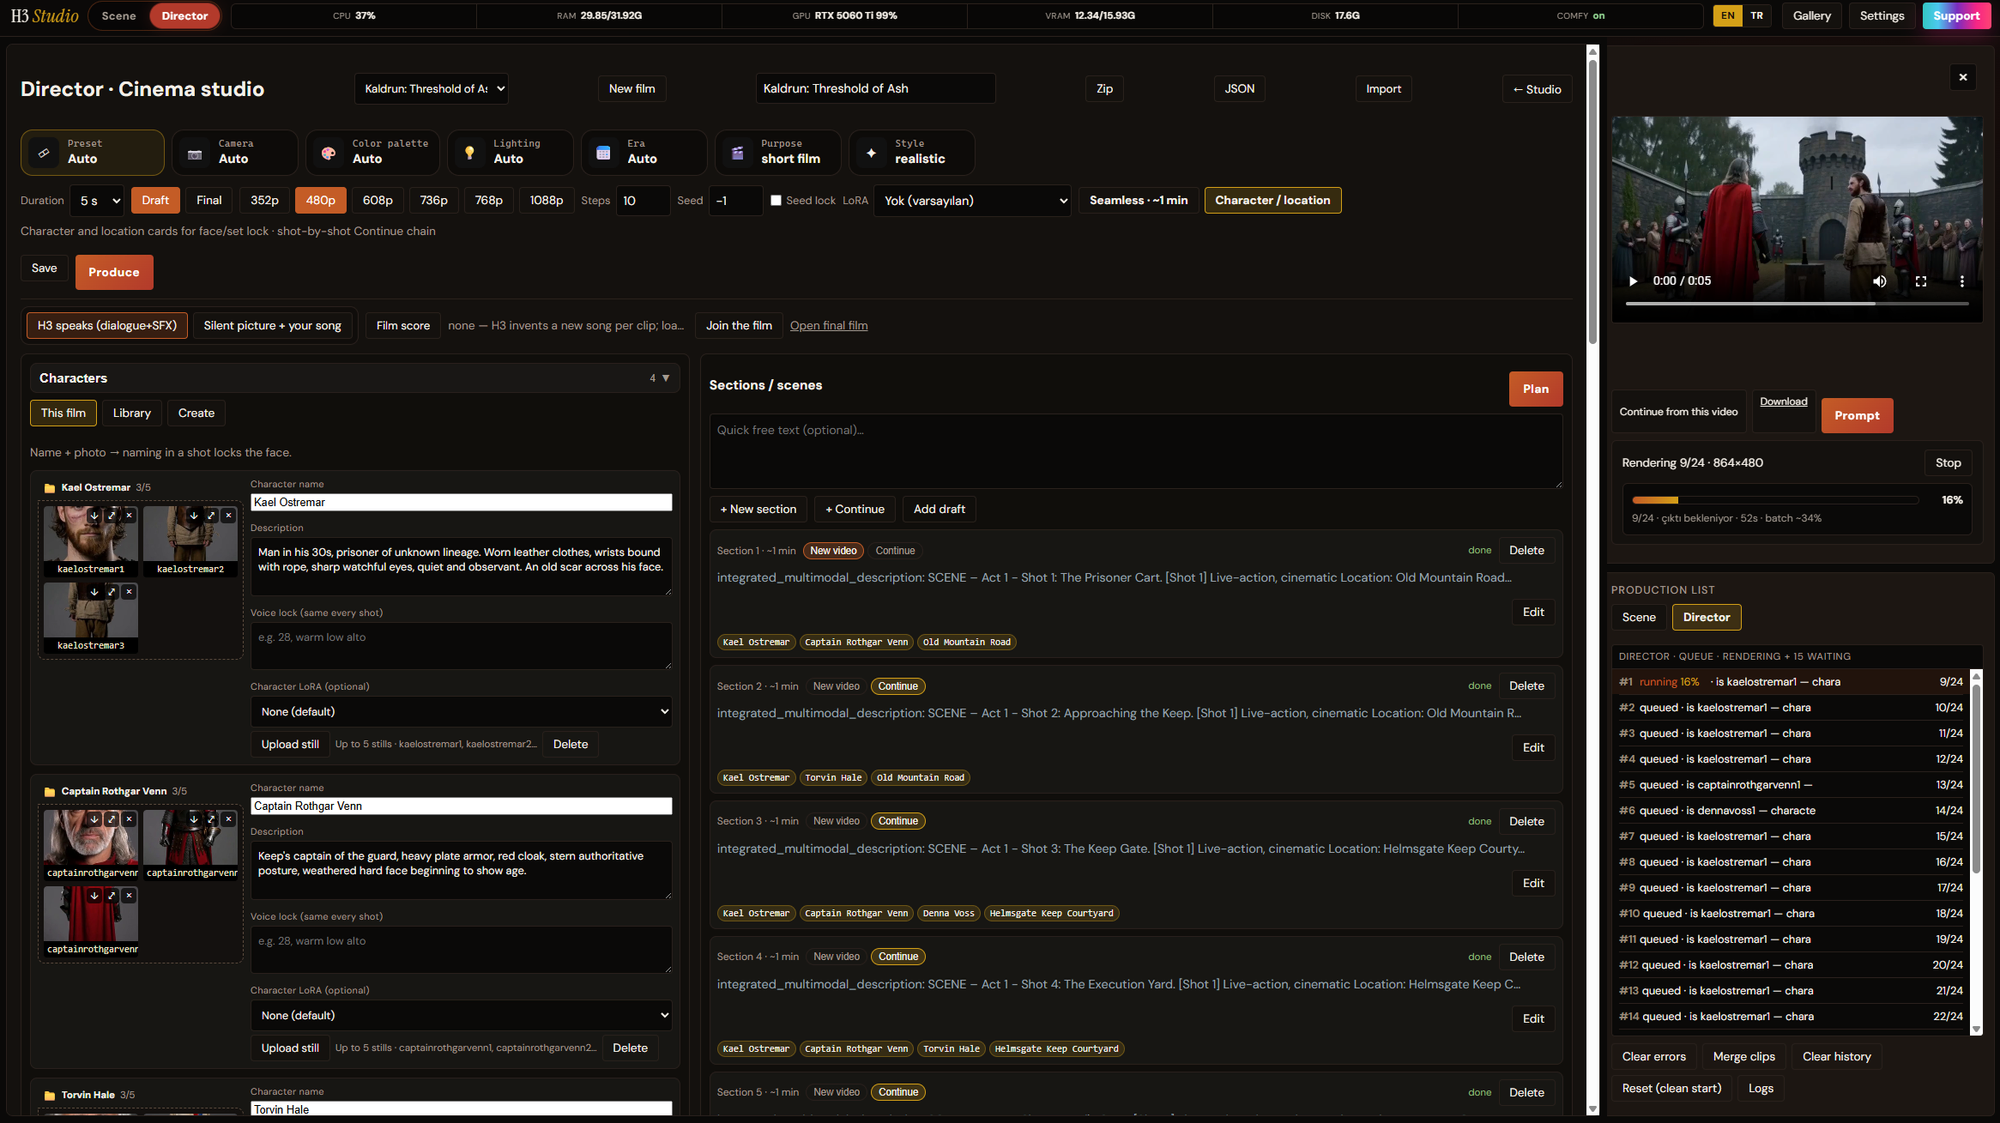
A comprehensive ComfyUI integration for Microsoft's VibeVoice text-to-speech model, enabling high-quality single and multi-speaker voice synthesis directly within your ComfyUI workflows.
Enter a description for your character (using the trigger word “img”) and optionally upload face photos, then provide a list of prompts—one per line—for each scene. The app creates a series of imag...
Open-source alternative to Higgsfield AI — Free AI image generation & cinema studio with 20+ models (Flux, SDXL, Midjourney, Ideogram). Self-hosted, customizable, MIT licensed.
Open-source alternative to Higgsfield AI — Free AI image generation & cinema studio with 20+ models (Flux, SDXL, Midjourney, Ideogram). Self-hosted, customizable, MIT licensed.
ThonburianTTS, a finetuned Thai TTS based on the E2-TTS and F5-TTS architectures, designed to improve pronunciation accuracy, alignment robustness, and zero-shot speaker adaptation for the Thai language
MOSS-TTSD is a spoken dialogue generation model designed for expressive multi-speaker synthesis. It features long-context modeling, flexible speaker control, and multilingual support, while enabling zero-shot voice cloning from short audio references.