Pinokio
FeedApps
Download Pinokio
Sign inCreate accountJoin

Apps

Announcements

View all

Official updates.

PM Codex
@ashvall•7h ago
Plaud + a self-hosted transcriber + Claude skill + PM CodexHi all! I wanted to share the bigger setup of my project management workflow using PM Codex, since a few pieces might be useful to people here even if you never touch PM Codex. The problem I have 1–3 hours of meetings a day. They’re bilingual, full of jargon, and people talk over each other. I record them on a Plaud Note Pro and Plaud Desktop, but I didn’t want Plaud’s subscription because I'm cheap. My local GPU was too weak to transcribe well, so I built my own pipeline in the cloud. Plaud Note Pro raw audio │ ▼ Claude scheduled task finds new recordings, submits them │ ▼ Cloud Transcriber (Modal) diarize · transcribe · name speakers │ ▼ Auricle (Claude) clean up · confirm speakers · draft MoM │ ▼ PM Codex change request to be reviewed 1. Plaud: raw audio only The official Plaud connector fetches the recording file. I don’t use any of Plaud’s paid transcription or summary features. 2. Claude scheduled task: hands-free pickup A Claude scheduled task runs in the cloud every hour during working hours on weekdays, so my computer doesn’t need to be on. Each run: Looks through my Plaud recordings from the last few days. Skips anything too short to be a meeting, anything unusually long, and anything that’s already been sent. Sends the remaining recordings to the transcriber and doesn’t wait for them to finish. Cleans up old transcription jobs. Reports back in one to three lines. It’s deliberately simple. It never asks questions, never touches PM Codex, and never guesses who’s speaking. It runs on a small, fast Claude model with automatic approval, so it costs almost nothing. By the time I sit down to review a meeting, the transcript is usually already waiting. 3. Cloud Transcriber: diarized ASR on Modal It runs on serverless GPUs that are billed per second and scale to zero. For each recording: pyannote works out who spoke when. Whisper large-v3, Qwen3-ASR and Qwen3-Omni (on vLLM) each transcribe every speaker turn. An ensemble keeps, for each turn, the version the engines agree on most. It flags likely hallucinations instead of silently deleting them. Voiceprints name the speakers. A speaker is named automatically only when the match is strong and clearly ahead of the next candidate. Otherwise it asks me. It costs about $0.25 per audio hour, which fits inside Modal’s free monthly credit for my usage. Before each job it checks how much credit is left and switches to a free fallback if there isn’t enough. 4. Auricle: the workflow layer (a Claude skill) When I say “Run auricle for a meeting at 2PM”, Claude picks up the finished transcript, or starts one if the scheduled task hasn’t picked up that recording yet. It cleans up the transcript using a glossary and the attendee list pulled from PM Codex. This fixes misheard names and acronyms. It asks me only about speakers it couldn’t identify, and shows example quotes so I can tell who’s who. It learns from my answers: confirmed speakers become voiceprints, and corrected terms go into the glossary. 5. Into PM Codex Auricle doesn’t write anything directly. It files one change request through the Claude bridge with the minutes, new tasks, risks and timeline updates. I review it and sign off in the app like any other change. What I learned Context beats model size. Giving the engines and the cleanup pass a glossary and attendee list did more than swapping engines. In my tests, the cleanup pass alone cut word errors by 3–6 points and recovered 20–35% more key terms. Combining engines beats any single one. My ensemble beat every engine on its own, and it also beat Plaud’s built-in transcript on the same audio. Crowded rooms are still hard. Every engine struggles with who said what when people talk over each other. Voiceprints are good for naming speakers but don’t fix that. Voiceprints are biometric data. If you build something similar, check your local privacy rules and make it easy for people to delete theirs. The transcriber and the Auricle skill aren’t public yet, but I’m happy to answer questions about the approach. If you’ve wired PM Codex into your own capture or transcription tools, I’d love to hear how!
Automated LoRA Studio
@manatheturipa•1d ago
🚀 Automated LoRA Studio — turn your videos into custom motion LoRAs. Upload a video, choose a supported Wan or LTX model, describe the movement, and click Prepare + train. The app automates: - ✂️ Cutting and formatting training clips - ✅ Frame count, size and FPS checks - ✍️ AI captions you can review and edit - ⚙️ Training caches and trainer setup - 💾 Checkpoints, resume, supported previews and export It brings together work you’d otherwise split between AI Video Clipper, manual FFmpeg commands, captioning tools and separate Wan/LTX training interfaces. No coding or manual training configs needed for the built-in workflow. Designed to make video LoRA creation approachable without technical experience. Free and open source. Your footage stays local. Compatible training hardware required. 👉 Get https://github.com/manat0912/automated-lora-studio.git
PhospheneFeatured
@bizarro•1d ago
Phosphene 4.19.5 - Hailuo H3 stays on tested versionsHailuo H3 used to install the newest version of every library it uses on the day you installed it, so one bad library update could break every new H3 install. H3 now installs the exact set of versions it was tested with, every time. This Update puts an existing H3 install on that set (about a minute, no weights downloaded). Your H3 videos come out the same as before. If H3's libraries ever drift again (a manual install, an interrupted Update), H3 stops in a second, before it uses the GPU, and the card offers Repair Hailuo H3 - one click, about a minute, every weight kept. LTX renders are not affected. Also since the 4.19 post: renders that a library update broke work again (4.19.4), Phosphene no longer touches your GitHub login (4.19.3), and Ingredients, LTX 2.3/2.5 switching and Linux on Apple Silicon landed with community fixes (4.19.2). Press Update in Pinokio, then restart. https://github.com/mrbizarro/Phosphene/releases/tag/v4.19.5
MiniMax H3 Studio
@mvrdvk•1d ago
Continuum Update (v2026‑10‑14)Continuum now supports two ways to build longer videos: Single Prompt: Repeat one prompt across the selected number of sections. Per Section: Write a separate prompt for each section. What’s improved Fixed an issue that could regenerate earlier sections when extending a video. Added shared character and setting text for every new section. Added Balanced (22 frames) and experimental Strong (39 frames) transition context. Continuations preserve the original seed, model settings, shared context and transition preset. The interface now shows existing duration + added duration = total duration. Validated with Studio Draft settings: 480p, 12 steps, 5 + 5 seconds. Saved-section reuse was confirmed, and both stickman fighters remained in the scene as the action continued into combat. Spectrum compatibility: Spectrum is bypassed in Continuum because it interfered with safe saved-section reuse. It remains available for ordinary H3 generation. Older Spectrum-enabled Continuum runs require a new series; existing videos are preserved. Continuum remains experimental. Character details, camera, lighting and motion can still drift. Strong context is not always better, so Balanced remains the default. Audio continuity and longer sequences need further testing. Update through Pinokio, restart Studio when the queue is idle, and refresh the page. ☕ Support development: https://buymeacoffee.com/erdindev
Captionz
@supersoniquestudio•3d ago
1-click Pinokio launcher for Captionz — batch image captioning with local Ollama vision models. What it does Installs and launches Captionz in one click: Install — clones mikecastrodemaria/Captionz into app/, creates a venv and installs the requirements (Pillow, NiceGUI, Gradio). No PyTorch: the models run in Ollama, or in a bundled llama.cpp server (see below). Start (web UI) — runs the NiceGUI interface (python app.py --ui web) and opens it. Start (Gradio UI) — runs the Gradio interface (python gradio_app.py), the same one used on Hugging Face Spaces, here with the Ollama backend. Update — resets the launcher and the app to their origin/main, refreshes deps. Reset — removes app/ (and its venv) to reinstall from scratch. Features (Captionz) Vision-model detection · composed prompts (caption type × length × 20 checkable options × character name) or custom prompt with a live preview · sources: local path, upload, clipboard paste · image preview · editable captions · skip / overwrite / append policy · prefix / suffix (trigger word) · live status (model loading, timer, percent, ETA) · max-tokens cap and thinking switch · dark mode · CLI and benchmark script. See the app repo for full docs. Requirements Pinokio installed. Either Ollama running on the machine (or reachable on the network: change the URL in the UI) with at least one vision model, for example ollama pull qwen3-vl:8b, or no Ollama at all: pick the backend "llama.cpp (sans Ollama)" in the UI. On first captioning Captionz downloads a prebuilt llama-server for your machine (CUDA / Vulkan / CPU / Metal, 150–500 MB) and the default model Qwen2.5-VL-3B-Instruct Q4_K_M (~2.9 GB) into app/llamacpp/. Other GGUF models can be downloaded from Hugging Face or imported from a local Ollama store from the "Modèles llama.cpp…" dialog. Captions are written next to each image as image.txt. How to use Install, then Start (web UI) and click Open Web UI. Pick the vision model, add a folder path (or upload / paste images). Choose a caption type, length and options; check the final prompt preview. Click Captionner tout. Edit any caption in the right panel and save. API Captionz has no HTTP API of its own. Two programmatic entry points exist in app/: Command line (Python, inside the launcher venv) python cli.py ./dataset --recursive --type "Booru tag list" --length short python cli.py ./dataset --model qwen3-vl:8b --option 3 --option 15 --prefix "mystyle, " python cli.py --list-models python cli.py --list-options Python (import the core) import sys; sys.path.insert(0, "app") from pathlib import Path from captionz_core import Settings, Job, make_backend, caption_job s = Settings.load() s.model = "qwen3-vl:8b" s.caption_type, s.caption_length = "Training caption (paragraph)", "long" job = caption_job(Job(Path("photo.jpg")), s, make_backend(s)) print(job.status, job.caption) Gradio UI API (when "Start (Gradio UI)" is running) Gradio exposes every event as an endpoint; open <url>/?view=api for the generated docs, or from Python: from gradio_client import Client, handle_file c = Client("http://127.0.0.1:7860") print(c.view_api()) JavaScript (Gradio client) import { Client } from "@gradio/client"; const c = await Client.connect("http://127.0.0.1:7860"); console.log(await c.view_api()); Curl (Ollama directly, same request Captionz sends) curl http://localhost:11434/api/chat -d '{ "model": "qwen3-vl:8b", "stream": false, "messages": [{"role": "user", "content": "Describe this image in one short sentence.", "images": ["<base64 image>"]}] }'
Iris-3B Studio
@thomas_eric•5d ago
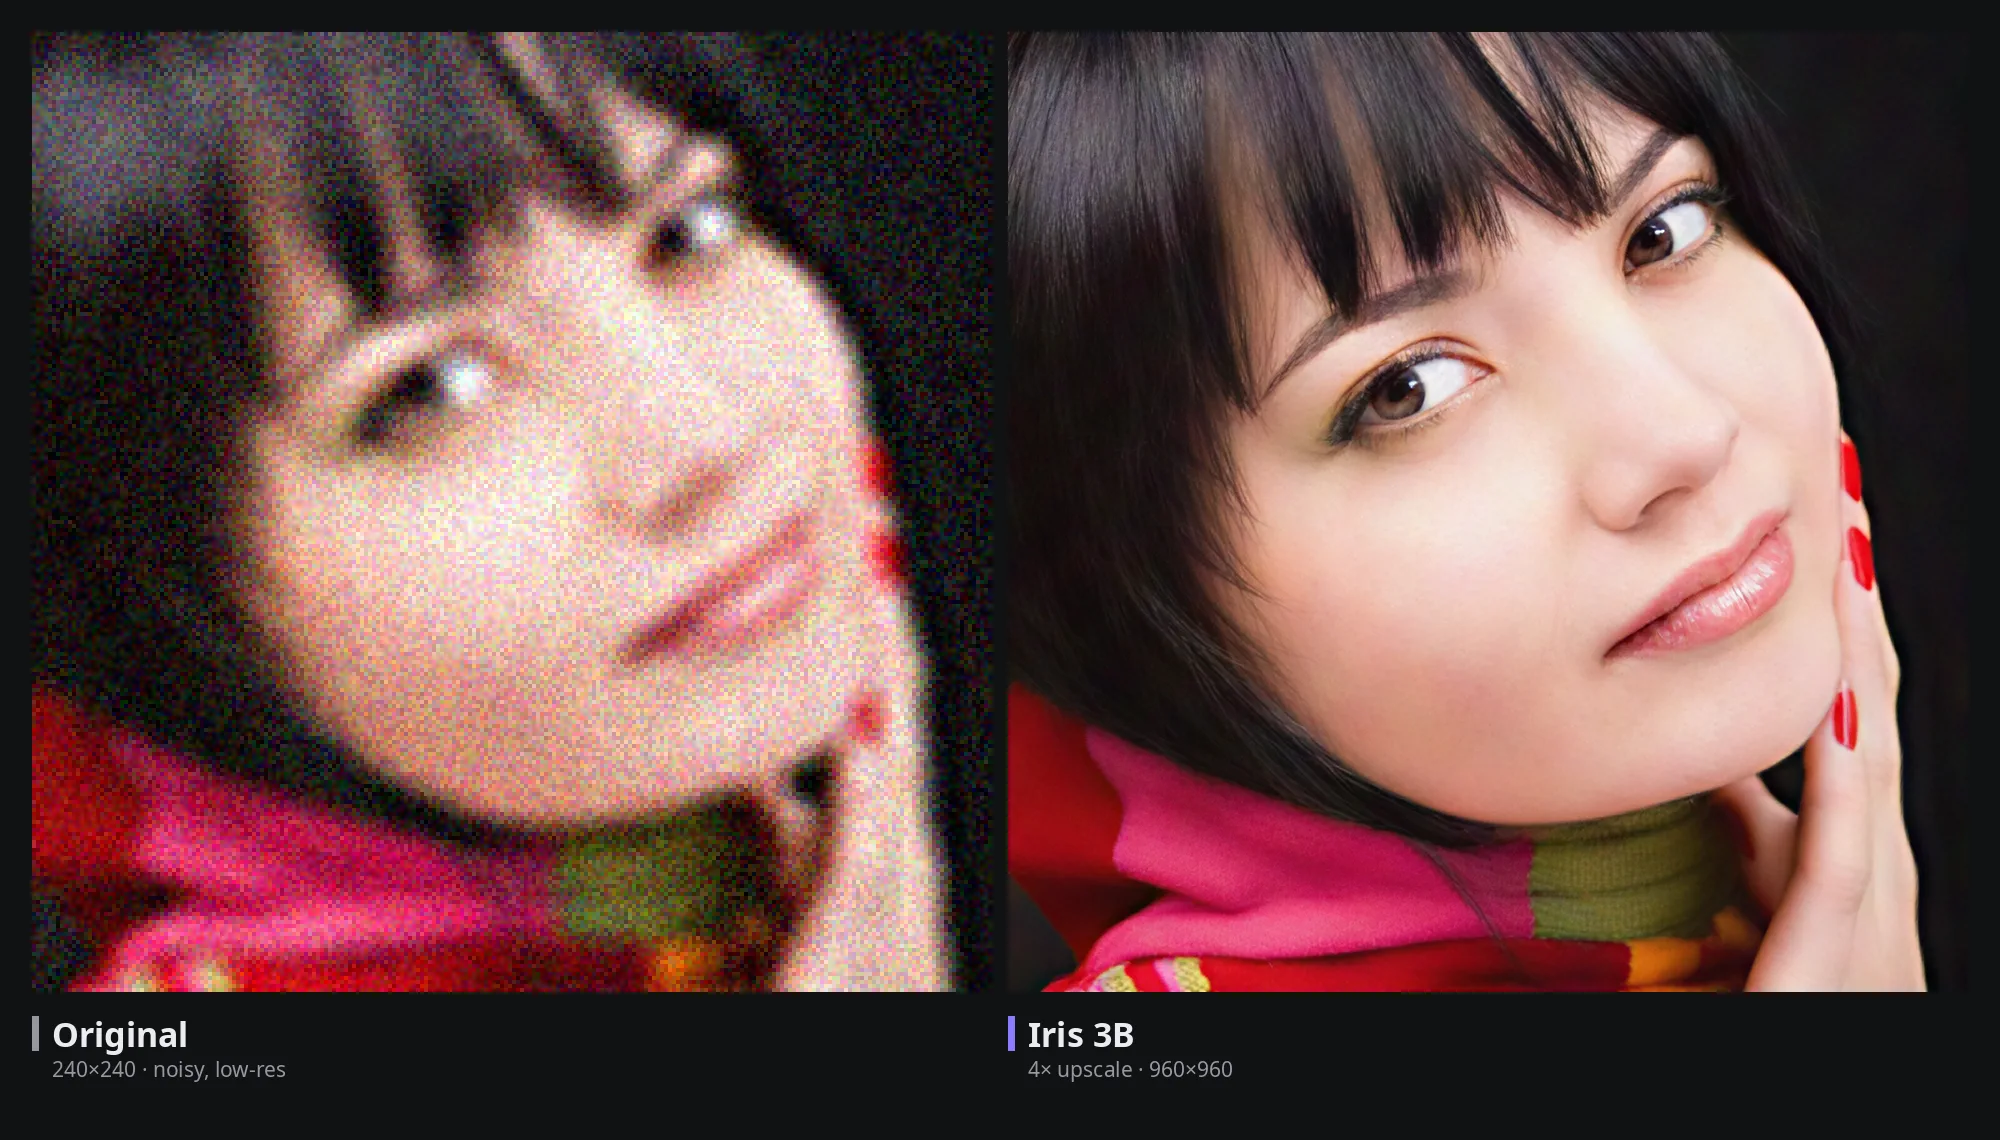
Iris 3B Studio is Now Available!Iris 3B Studio is Now Available! Not only is a incredible text-to-image model, but it also has upscaling capabilities and depth map generation!
Type:plugin
apipluginAll
Platform:Linux
AllmacOSWindowsLinux
GPU:NVIDIA
AllNVIDIAAMDApple
Sort by
RecommendedLatestCheck-ins
#ai191#tts60#image-generation46#video-generation40#137#utility35#music33#próba27
No apps found.

Pulse

View all

The latest posts from across Pinokio.

اصنع لي فيديو كوميدي بموسيقى و صوت
@mohaned · Wan2GP1
2cris-moi une chanson rap conscient hardcore comme dans les années 2000
@bigarnaud · SongGeneration Studio1
ComfyUI: ERROR: Could not find a version that satisfies the requirement torch (from versions: none)
@vinhproduction · ComfyUI
App: ComfyUI (comfyui-pinokio.git) Repo: https://github.com/fakumax/comfyui-pinokio.git Generated: 20...
Plaud + a self-hosted transcriber + Claude skill + PM Codex
@ashvall · PM Codex
Hi all! I wanted to share the bigger setup of my project management workflow using PM Codex, since a ...
Issue report: Wan2GP
@gullid77 · Wan2GP1
App: Wan2GP (wan.git) Repo: https://github.com/pinokiofactory/wan.git Generated: 2026-10-16T07:19:55....

Radar

View all

Projects getting attention.

Followed·2 min
God's Eye View
A live 3D intelligence console for planet Earth.
Installable
Followed·5 min
LTX-Desktop-WanGP
Pinokio launcher for LTX-Desktop-WanGP (local video generation with WanGP backend)
Installable
Followed·11 min
Wan2GP
1-click WanGP Launcher. Super Optimized Gradio UI for AI video creation for GPU poor machines (6GB+ VRAM). Supports Wan 2.1/2.2, Qwen, Hunyuan Video, LTX Video and Flux. https://github.com/deepbeepmeep/Wan2GP
Installable
Followed·14 min
Wan2GP - AMD
[AMD ONLY] Super Optimized Gradio UI for AI video creation for GPU poor machines (6GB+ VRAM). Supports Wan 2.1/2.2, Qwen, Hunyuan Video, LTX Video, Flux and more. (On Windows supported by all dedicated AMD GPUs from RDNA 2 - RDNA 4)
Installable
Followed·22 min
FaceFusion
Industry leading face manipulation platform
Installable
Pinokio
PrivacyTerms
FeedApps